


Commit ·
2aeedcc
1
Parent(s): 602f999
Update README.md
Browse files
README.md
CHANGED
|
@@ -14,7 +14,14 @@ widget:
|
|
| 14 |
|
| 15 |
# nlpconnect/vit-gpt2-image-captioning
|
| 16 |
|
| 17 |
-
This is an image captioning model
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 18 |
|
| 19 |
|
| 20 |
# Sample running code
|
|
@@ -58,3 +65,21 @@ predict_step(['doctor.e16ba4e4.jpg']) # ['a woman in a hospital bed with a woman
|
|
| 58 |
|
| 59 |
```
|
| 60 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 14 |
|
| 15 |
# nlpconnect/vit-gpt2-image-captioning
|
| 16 |
|
| 17 |
+
This is an image captioning model trained by @ydshieh in [flax ](https://github.com/huggingface/transformers/tree/main/examples/flax/image-captioning) this is pytorch version of [this](https://huggingface.co/ydshieh/vit-gpt2-coco-en-ckpts).
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
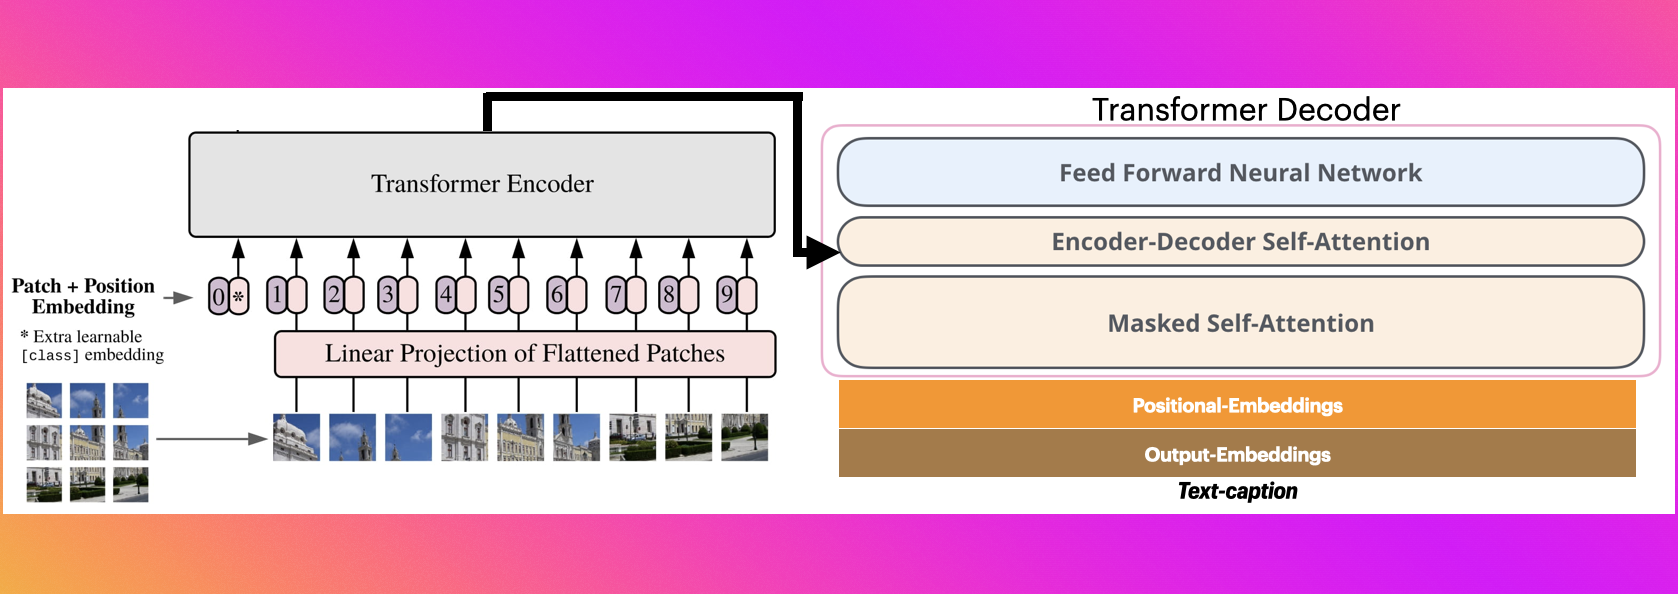
# The Illustrated Image Captioning using transformers
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
## https://ankur3107.github.io/blogs/the-illustrated-image-captioning-using-transformers/
|
| 25 |
|
| 26 |
|
| 27 |
# Sample running code
|
|
|
|
| 65 |
|
| 66 |
```
|
| 67 |
|
| 68 |
+
# Sample running code using transformers pipeline
|
| 69 |
+
|
| 70 |
+
```python
|
| 71 |
+
|
| 72 |
+
from transformers import pipeline
|
| 73 |
+
|
| 74 |
+
image_to_text = pipeline("image-to-text", model="nlpconnect/vit-gpt2-image-captioning")
|
| 75 |
+
|
| 76 |
+
image_to_text("https://ankur3107.github.io/assets/images/image-captioning-example.png")
|
| 77 |
+
|
| 78 |
+
# [{'generated_text': 'a soccer game with a player jumping to catch the ball '}]
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
```
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
# Contact for any help
|
| 85 |
+
* https://huggingface.co/ankur310794
|