# BEiT
## 概述
BEiT 模型由 Hangbo Bao、Li Dong 和 Furu Wei 在 [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254) 中提出。受 BERT 的启发,BEiT 是首篇证明视觉 Transformer(ViT)的自监督预训练性能优于监督预训练性能的工作。与在 [原始 ViT 论文](https://huggingface.co/papers/2010.11929) 中通过预测图像类别来预训练模型不同,BEiT 模型在给定掩码块的情况下,被预训练以预测来自 OpenAI [DALL-E 模型](https://huggingface.co/papers/2102.12092) 码本的视觉 token。
该论文的摘要如下:
*我们提出了一种自监督视觉表示模型 BEiT,即 Bidirectional Encoder representation from Image Transformers(基于图像 Transformer 的双向编码器表示)。借鉴自然语言处理领域中开发的 BERT,我们提出了一种掩码图像建模任务来预训练视觉 Transformer。具体而言,在我们的预训练中,每张图像具有两个视图,即图像块(例如 16x16 像素)和视觉标记(即离散标记)。我们首先将原始图像“标记化”为视觉标记。然后,我们随机掩蔽一些图像块,并将它们输入骨干 Transformer。预训练的目标是基于被破坏的图像块恢复原始的视觉标记。在预训练 BEiT 之后,我们在预训练编码器之上添加任务层,直接在下游任务上微调模型参数。图像分类和语义分割的实验结果表明,我们的模型与以往的预训练方法相比取得了具有竞争力的结果。例如,base 尺寸的 BEiT 在 ImageNet-1K 上达到了 83.2% 的 top-1 准确率,显著优于相同设置下从头训练的 DeiT(81.8%)。此外,large 尺寸的 BEiT 仅使用 ImageNet-1K 就获得了 86.3% 的准确率,甚至超过了在 ImageNet-22K 上进行有监督预训练的 ViT-L(85.2%)。*
该模型由 [nielsr](https://huggingface.co/nielsr) 贡献。原始代码可在[此处](https://github.com/microsoft/unilm/tree/master/beit)找到。
## 使用技巧
- BEiT 模型是标准的 Vision Transformer,但采用自监督方式而非监督方式进行预训练。在 ImageNet-1K 和 CIFAR-100 上进行微调时,其性能优于[原始模型(ViT)](vit)以及[Data-efficient Image Transformers (DeiT)](deit)。您可以在此处查看有关推理以及在自定义数据上进行微调的演示笔记本[here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)(只需将[ViTImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/vit#transformers.ViTImageProcessor)替换为[BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor),并将[ViTForImageClassification](/docs/transformers/v5.23.0/zh/model_doc/vit#transformers.ViTForImageClassification)替换为[BeitForImageClassification](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForImageClassification)即可)。
- 此外,还有一个演示笔记本,展示了如何将 DALL-E 的图像分词器与 BEiT 结合,以执行掩码图像建模。您可以在[此处](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BEiT)找到它。
- 由于 BEiT 模型要求每张图片具有相同的大小(分辨率),可以使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 对图像进行缩放(或重新缩放)和归一化,以适配模型。
- 预训练或微调过程中使用的 patch 分辨率和图像分辨率均体现在每个检查点的名称中。例如,`microsoft/beit-base-patch16-224` 指的是一个 base 规模的架构,其 patch 分辨率为 16x16,微调分辨率为 224x224。所有检查点均可在 [hub](https://huggingface.co/models?search=microsoft/beit) 上找到。
- 可用的检查点分为以下三种情况:(1) 仅在 [ImageNet-22k](http://www.image-net.org/)(包含 1400 万张图像和 2.2 万个类别的数据集)上进行预训练;(2) 在 ImageNet-22k 上进行预训练后,又在该数据集上进行了微调;(3) 在 ImageNet-22k 上进行预训练后,又在 [ImageNet-1k](http://www.image-net.org/challenges/LSVRC/2012/)(也称为 ILSVRC 2012,包含 130 万张图像和 1,000 个类别的数据集)上进行了微调。
- BEiT 使用相对位置嵌入,其灵感来源于 T5 模型。在预训练期间,作者在多个自注意力层之间共享相对位置偏置。在微调期间,每一层的相对位置偏置都会使用预训练后获得的共享相对位置偏置进行初始化。请注意,如果想要从头开始预训练一个模型,需要将 [BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig) 的 `use_relative_position_bias` 或 `use_relative_position_bias` 属性设置为 `True`,以便添加位置嵌入。
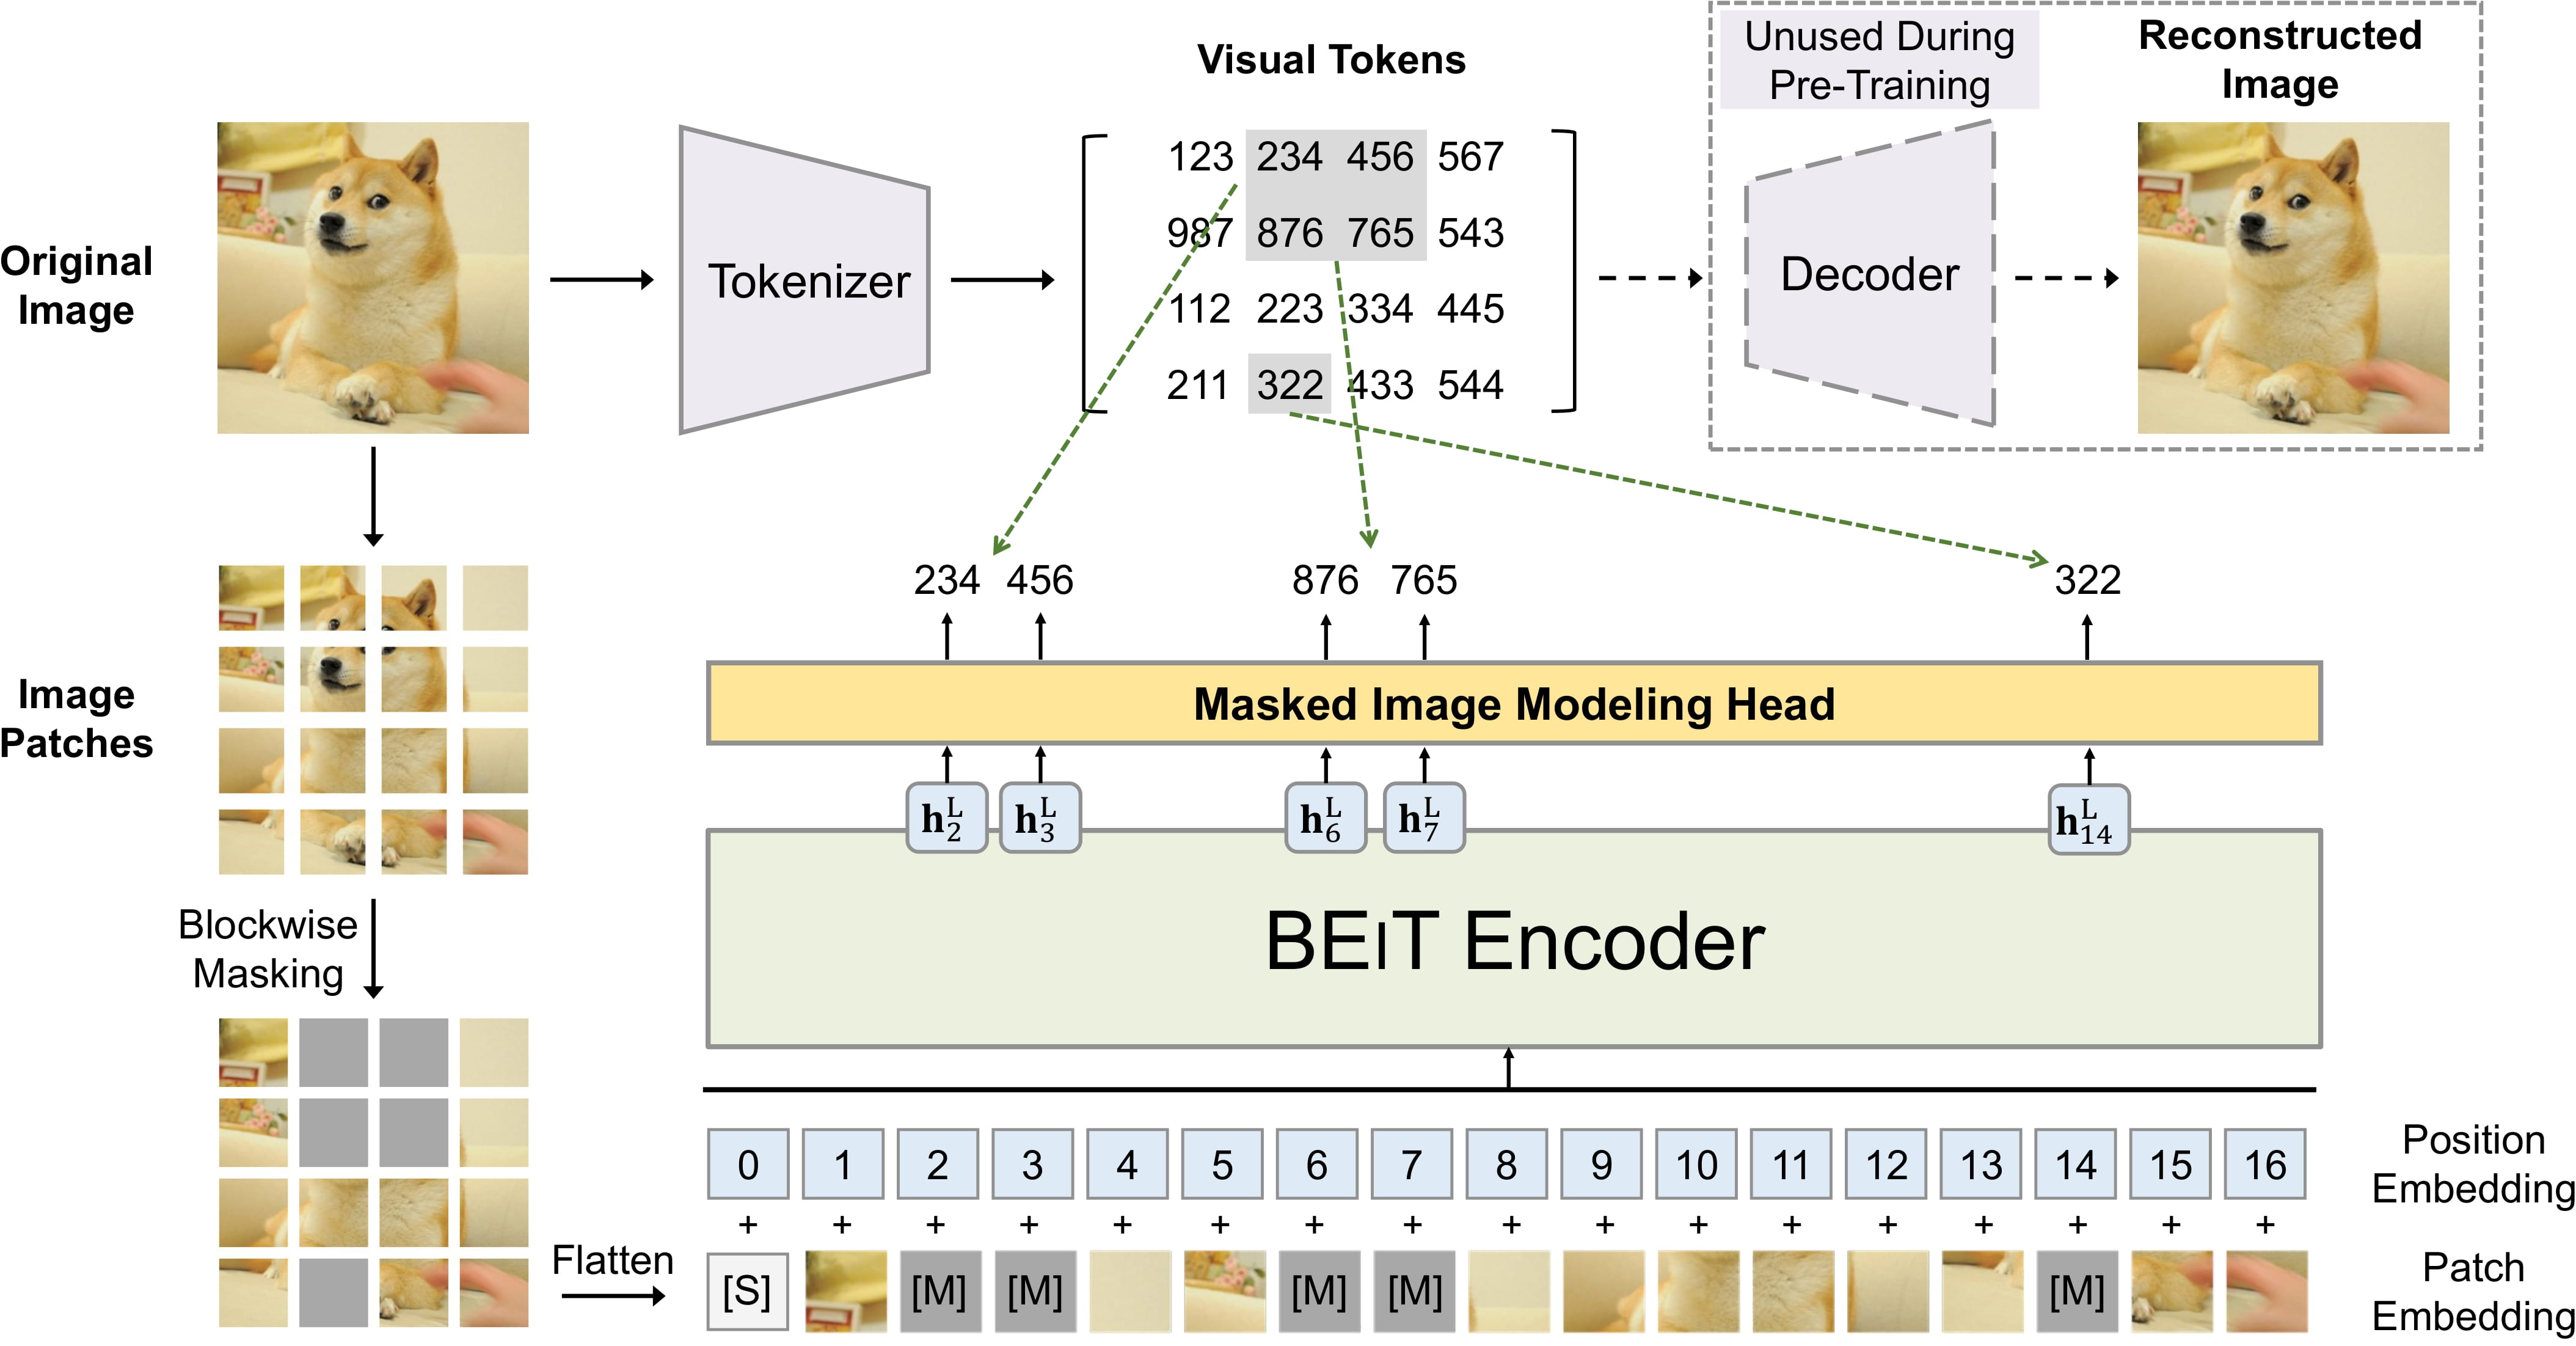 BEiT 预训练。摘自原始论文。
### 使用缩放点积注意力(SDPA)
PyTorch 在 `torch.nn.functional` 中包含了原生的缩放点积注意力(SDPA)算子。该函数涵盖了多种实现方式,可根据输入和所用硬件进行应用。有关更多信息,请参阅[官方文档](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)或[GPU 推理](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)页面。
当存在可用实现时,`torch>=2.1.1` 默认使用 SDPA,但您也可以在 `from_pretrained()` 中设置 `attn_implementation="sdpa"` 以显式请求使用 SDPA。
```python
from transformers import BeitForImageClassification
model = BeitForImageClassification.from_pretrained("microsoft/beit-base-patch16-224", attn_implementation="sdpa", device_map="auto")
...
```
为了获得最佳加速效果,我们建议以半精度(例如 `torch.float16` 或 `torch.bfloat16`)加载模型。
在本地基准测试(NVIDIA GeForce RTX 2060-8GB、PyTorch 2.5.1、操作系统 Ubuntu 20.04)中,使用 `float16` 和 `microsoft/beit-base-patch16-224` 模型,我们在训练和推理过程中观察到以下改进:
#### 训练
| num_training_steps | batch_size | image_size | is_cuda | 每个批次的耗时(eager - 秒) | 每个批次的耗时(sdpa - s) | 加速比(%) | Eager 峰值内存 (MB) | SDPA 峰值内存 (MB) | 内存节省(%) |
|--------------------|------------|--------------|---------|----------------------------|---------------------------|-------------|----------------------|--------------------|----------------|
| 50 | 2 | (1048, 640) | True | 0.984 | 0.746 | 31.975 | 6738.915 | 4319.886 | 55.998 |
#### 推理
| 图像批处理大小 | Eager(秒/迭代) | Eager CI,% | Eager 内存(MB) | SDPA(秒/迭代) | SDPA CI,% | SDPA 内存(MB) | SDPA 加速 | SDPA 节省的内存 (%) |
|-------------------:|-----------------:|:--------------|--------------------:|----------------:|:-------------|-------------------:|---------------:|----------------------:|
| 1 | 0.012 | ±0.3% | 3.76657e+08 | 0.011 | ±0.5% | 3.75739e+08 | 1.05 | 0.244 |
| 4 | 0.013 | ±0.1% | 4.03147e+08 | 0.011 | ±0.2% | 3.90554e+08 | 1.178 | 3.225 |
| 16 | 0.045 | ±0.1% | 4.96697e+08 | 0.035 | ±0.1% | 4.51232e+08 | 1.304 | 10.076 |
| 32 | 0.088 | ±0.1% | 6.24417e+08 | 0.066 | ±0.1% | 5.33488e+08 | 1.325 | 17.044 |
## 资源
一份官方 Hugging Face 和社区(以 🌎 标识)资源列表,帮助你快速上手 BEiT。
- [BeitForImageClassification](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForImageClassification) 受此 [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb) 支持。
- 另请参阅:[图像分类任务指南](../tasks/image_classification)
**语义分割**
- [语义分割任务指南](../tasks/semantic_segmentation)
如果您有兴趣提交资源以收录在此处,请随时发起 Pull Request,我们将对其进行审核!理想情况下,该资源应展示一些新内容,而不是重复现有资源。
## BEiT 特定输出[[transformers.models.beit.modeling_beit.BeitModelOutputWithPooling]]
#### transformers.models.beit.modeling_beit.BeitModelOutputWithPooling[[transformers.models.beit.modeling_beit.BeitModelOutputWithPooling]]
```python
transformers.models.beit.modeling_beit.BeitModelOutputWithPooling(last_hidden_state: typing.Optional[torch.Tensor] = None, pooler_output: typing.Optional[torch.Tensor] = None, hidden_states: tuple[torch.Tensor, ...] | None = None, attentions: tuple[torch.Tensor, ...] | None = None)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L54)
**参数:**
last_hidden_state (形状为 `(batch_size, sequence_length, hidden_size)` 的 `torch.Tensor`):模型最后一层输出的隐藏状态序列。
pooler_output (`torch.Tensor`,形状为 `(batch_size, hidden_size)`):如果 *config.use_mean_pooling* 设置为 True,则为 patch token 最后一层隐藏状态的平均值(不包括 *[CLS]* token)。如果设置为 False,则返回 *[CLS]* token 的最终隐藏状态。
hidden_states (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回):一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每个层输出的一个张量),形状为 `(batch_size, sequence_length, hidden_size)`。模型在每层输出处的隐藏状态,以及可选的初始嵌入输出。
attentions (`tuple(torch.Tensor)`,*可选*,在传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回):一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。注意力 softmax 之后的注意力权重,用于在自注意力头中计算加权平均值。
[BeitModel](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitModel) 的输出类。
## BeitConfig[[transformers.BeitConfig]]
#### transformers.BeitConfig[[transformers.BeitConfig]]
```python
transformers.BeitConfig(transformers_version: str | None = None, architectures: list[str] | None = None, output_hidden_states: bool | None = False, return_dict: bool | None = True, dtype: str | torch.dtype | None = None, chunk_size_feed_forward: int = 0, is_encoder_decoder: bool = False, id2label: dict[int, str] | dict[str, str] | None = None, label2id: dict[str, int] | dict[str, str] | None = None, problem_type: Literal['regression', 'single_label_classification', 'multi_label_classification'] | None = None, vocab_size: int = 8192, hidden_size: int = 768, num_hidden_layers: int = 12, num_attention_heads: int = 12, intermediate_size: int = 3072, hidden_act: str = 'gelu', hidden_dropout_prob: float | int = 0.0, attention_probs_dropout_prob: float | int = 0.0, initializer_range: float = 0.02, layer_norm_eps: float = 1e-12, image_size: int | list[int] | tuple[int, int] = 224, patch_size: int | list[int] | tuple[int, int] = 16, num_channels: int = 3, use_mask_token: bool = False, use_absolute_position_embeddings: bool = False, use_relative_position_bias: bool = False, use_shared_relative_position_bias: bool = False, layer_scale_init_value: float = 0.1, drop_path_rate: float | int = 0.1, use_mean_pooling: bool = True, pool_scales: list[int] | tuple[int, ...] = (1, 2, 3, 6), use_auxiliary_head: bool = True, auxiliary_loss_weight: float = 0.4, auxiliary_channels: int = 256, auxiliary_num_convs: int = 1, auxiliary_concat_input: bool = False, semantic_loss_ignore_index: int = 255, _out_features: list[str] | None = None, _out_indices: list[int] | None = None, add_fpn: bool = False, reshape_hidden_states: bool = True)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/configuration_beit.py#L25)
**参数:**
vocab_size (`int`,*可选*,默认为 `8192`):模型的词汇表大小。定义了 `input_ids` 可以表示的不同 token 数量。
hidden_size (`int`,*可选*,默认为 `768`):隐藏表示的维度。
num_hidden_layers (`int`,*可选*,默认为 `12`):Transformer 解码器中的隐藏层数。
num_attention_heads (`int`,*可选*,默认为 `12`):Transformer 解码器中每个注意力层的注意力头数量。
intermediate_size (`int`,*可选*,默认值为 `3072`):MLP 表示的维度。
hidden_act (`str`,*可选*,默认为 `gelu`):解码器中的非线性激活函数(函数或字符串)。例如,`"gelu"`、`"relu"`、`"silu"` 等。
hidden_dropout_prob (`Union[float, int]`,*可选*,默认值为 `0.0`):嵌入层、编码器和池化器中所有全连接层的 dropout 概率。
attention_probs_dropout_prob (`Union[float, int]`,*可选*,默认值为 `0.0`):注意力概率的 dropout 比率。
initializer_range (`float`,*可选*,默认值为 `0.02`):用于初始化所有权重矩阵的 truncated_normal_initializer 的标准差。
layer_norm_eps (`float`, *可选*,默认为 `1e-12`):层归一化层所使用的 epsilon。
image_size (`Union[int, list[int], tuple[int, int]]`,*可选*,默认为 `224`):每张图片的尺寸(分辨率)。
patch_size (`Union[int, list[int], tuple[int, int]]`,*可选*,默认为 `16`):每个 patch 的大小(分辨率)。
num_channels (`int`,*可选*,默认为 `3`):输入通道数。
use_mask_token (`bool`,*可选*,默认为 `False`):是否使用掩码标记进行掩码图像建模。
use_absolute_position_embeddings (`bool`,*可选*,默认为 `False`):是否使用绝对位置嵌入。
use_relative_position_bias (`bool`,*可选*,默认为 `False`):是否在自注意力层中使用 T5 风格的相对位置嵌入。
use_shared_relative_position_bias (`bool`,*可选*,默认为 `False`):是否在整个 Transformer 的所有自注意力层中使用相同的相对位置嵌入。
layer_scale_init_value (`float`, *可选*,默认为 `0.1`):自注意力层中使用的缩放比例。基础模型为 0.1,大型模型为 1e-6。设置为 0 可禁用层缩放。
drop_path_rate (`Union[float, int]`,*可选*,默认为 `0.1`):用于 patch 融合的 drop path 比率。
use_mean_pooling (`bool`,*可选*,默认为 `True`):在应用分类头之前,是否对补丁的最终隐藏状态进行平均池化,而不是使用 CLS 令牌的最终隐藏状态。
pool_scales (`tuple[int]`,*可选*,默认为 `[1, 2, 3, 6]`):应用于最后一个特征图的池化金字塔模块(Pooling Pyramid Module)所使用的池化比例。
use_auxiliary_head (`bool`, *可选*, 默认为 `True`) : 是否在训练期间使用辅助头。
auxiliary_loss_weight (`float`, *可选*, 默认值为 0.4) : 辅助头交叉熵损失的权重。
auxiliary_channels (`int`,*可选*,默认为 256):辅助头中使用的通道数。
auxiliary_num_convs (`int`,*可选*,默认为 1):辅助头中使用的卷积层数。
auxiliary_concat_input (`bool`,*可选*,默认为 `False`):是否将辅助头的输出与输入拼接,然后再送入分类层。
semantic_loss_ignore_index (`int`,*可选*,默认为 `255`):语义分割模型的损失函数所忽略的索引。
add_fpn (`bool`,*可选*,默认为 `False`):是否将 FPN 作为骨干网络的一部分。仅适用于 `BeitBackbone`。
reshape_hidden_states (`bool`, *可选*,默认为 `True`) : 当模型用作骨干网络时,是否将特征图重塑为形状为 `(batch_size, hidden_size, height, width)` 的 4D 张量。如果为 `False`,特征图将是形状为 `(batch_size, seq_len, hidden_size)` 的 3D 张量。仅对 `BeitBackbone` 有效。
这是用于存储 BeitModel 配置的类。它根据指定的参数实例化 Beit 模型,从而定义模型架构。使用默认值实例化配置,将得到与 [microsoft/beit-base-patch16-224-pt22k](https://huggingface.co/microsoft/beit-base-patch16-224-pt22k) 类似的配置。
配置对象继承自 [PreTrainedConfig](/docs/transformers/v5.23.0/zh/main_classes/configuration#transformers.PreTrainedConfig),可用于控制模型输出。有关更多信息,请参阅 [PreTrainedConfig](/docs/transformers/v5.23.0/zh/main_classes/configuration#transformers.PreTrainedConfig) 的文档。
示例:
```python
>>> from transformers import BeitConfig, BeitModel
>>> # Initializing a BEiT beit-base-patch16-224-pt22k style configuration
>>> configuration = BeitConfig()
>>> # Initializing a model (with random weights) from the beit-base-patch16-224-pt22k style configuration
>>> model = BeitModel(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
## BeitImageProcessor[[transformers.BeitImageProcessor]]
#### transformers.BeitImageProcessor[[transformers.BeitImageProcessor]]
```python
transformers.BeitImageProcessor(**kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/image_processing_beit.py#L50)
**参数:**
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`, *kwargs*, *可选*, 默认为 `True`) : 是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*,默认为 `{'height' : 224, 'width': 224}`):描述输入到模型的最大尺寸。
default_to_square (`bool`,*kwargs*,*可选*,默认为 `True`):当 size 为整数时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*,默认为 `{'height' : 224, 'width': 224}`):应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*,默认值为 `3`) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*,默认为 `True`):是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*,默认为 `0.00392156862745098`) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`,*kwargs*,*可选*,默认为 `True`):是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*,默认为 `[0.5, 0.5, 0.5]`):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*,默认为 `[0.5, 0.5, 0.5]`) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*,默认为 `False`) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
do_reduce_labels (`bool`, *kwargs*, *可选*,默认为 `self.do_reduce_labels`) : 是否将所有分割图的标签值减 1。通常用于 0 表示背景且背景本身不包含在数据集所有类别中的数据集(例如 ADE20k)。背景标签将被替换为 255。
构建一个 BeitImageProcessor 图像处理器。
#### preprocess[[transformers.BeitImageProcessor.preprocess]]
```python
preprocess(images: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor']], segmentation_maps: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor'], NoneType] = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/image_processing_beit.py#L70)
**参数:**
images (`Union[PIL.Image.Image, numpy.ndarray, torch.Tensor, list[PIL.Image.Image], list[numpy.ndarray], list[torch.Tensor]]`) : 要预处理的图像。期望输入单张或一批像素值在 0 到 255 之间的图像。如果传入的图像像素值在 0 到 1 之间,请设置 `do_rescale=False`。
segmentation_maps (`ImageInput`,*可选*):要预处理的分割图。
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`,*kwargs*,*可选*):是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`, *kwargs*, *可选*) : 当 size 为 int 时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*) : 是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
do_reduce_labels (`bool`, *kwargs*, *可选*,默认为 `self.do_reduce_labels`) : 是否将所有分割图的标签值减 1。通常用于 0 表示背景且背景本身不包含在数据集所有类别中的数据集(例如 ADE20k)。背景标签将被替换为 255。
**返回:** `~image_processing_base.BatchFeature`
- **data** (`dict`) -- 由 __call__ 方法返回的列表/数组/张量字典(例如 'pixel_values')。
- **tensor_type** (`Union[None, str, TensorType]`,*可选*) -- 您可以在此处指定 tensor_type,以便在初始化时将 PyTorch/Numpy 张量中的整数列表进行转换。
#### post_process_semantic_segmentation[[transformers.BeitImageProcessor.post_process_semantic_segmentation]]
```python
post_process_semantic_segmentation(outputs, target_sizes: list[tuple] | None = None, return_segmentation_scores: bool = False)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/image_processing_beit.py#L183)
**参数:**
outputs ([BeitForSemanticSegmentation](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForSemanticSegmentation)):模型的原始输出。
target_sizes (`list[Tuple]`,长度为 `batch_size`,*可选*) : 与每个预测所需的最终尺寸(高度、宽度)对应的元组列表。如果未设置,预测结果将不会被调整大小。
return_segmentation_scores (`bool`,*可选*,默认为 `False`):是否同时返回分割分数和分割图。当为 `True` 时,返回列表中的每个元素都是一个 `SemanticSegmentationPostProcessorOutput`,包含字段 `segmentation`(类别 ID,形状为 `(height, width)`)和 `segmentation_scores`(形状为 `(num_classes, height, width)`)。
**返回:** `list[torch.Tensor]` 或 `list[SemanticSegmentationPostProcessorOutput]`
当 `return_segmentation_scores=False`(默认值)时,返回一个长度为 `batch_size` 的列表,其中每个元素都是形状为 `(height, width)` 且包含类别 ID 的分割图。当 `return_segmentation_scores=True` 时,返回一个 `SemanticSegmentationPostProcessorOutput` 列表,包含字段 `segmentation`(类别 ID,形状为 `(height, width)`)和 `segmentation_scores`(形状为 `(num_classes, height, width)`)。在这两种情况下,`(height, width)` 均对应目标尺寸(如果指定了 `target_sizes`)。
将 [BeitForSemanticSegmentation](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForSemanticSegmentation) 的输出转换为语义分割图。
## BeitImageProcessorPil[[transformers.BeitImageProcessorPil]]
#### transformers.BeitImageProcessorPil[[transformers.BeitImageProcessorPil]]
```python
transformers.BeitImageProcessorPil(**kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/image_processing_pil_beit.py#L53)
**参数:**
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`, *kwargs*, *可选*, 默认为 `True`) : 是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*,默认为 `{'height' : 224, 'width': 224}`):描述输入到模型的最大尺寸。
default_to_square (`bool`,*kwargs*,*可选*,默认为 `True`):当 size 为整数时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*,默认为 `{'height' : 224, 'width': 224}`):应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*,默认值为 `3`) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*,默认为 `True`):是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*,默认为 `0.00392156862745098`) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`,*kwargs*,*可选*,默认为 `True`):是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*,默认为 `[0.5, 0.5, 0.5]`):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*,默认为 `[0.5, 0.5, 0.5]`) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*,默认为 `False`) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
do_reduce_labels (`bool`, *kwargs*, *可选*,默认为 `self.do_reduce_labels`) : 是否将所有分割图的标签值减 1。通常用于 0 表示背景且背景本身不包含在数据集所有类别中的数据集(例如 ADE20k)。背景标签将被替换为 255。
构建一个 BeitImageProcessor 图像处理器。
#### preprocess[[transformers.BeitImageProcessorPil.preprocess]]
```python
preprocess(images: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor']], segmentation_maps: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor'], NoneType] = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/image_processing_pil_beit.py#L73)
**参数:**
images (`Union[PIL.Image.Image, numpy.ndarray, torch.Tensor, list[PIL.Image.Image], list[numpy.ndarray], list[torch.Tensor]]`) : 要预处理的图像。期望输入单张或一批像素值在 0 到 255 之间的图像。如果传入的图像像素值在 0 到 1 之间,请设置 `do_rescale=False`。
segmentation_maps (`ImageInput`,*可选*):要预处理的分割图。
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`,*kwargs*,*可选*):是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`, *kwargs*, *可选*) : 当 size 为 int 时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*) : 是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
do_reduce_labels (`bool`, *kwargs*, *可选*,默认为 `self.do_reduce_labels`) : 是否将所有分割图的标签值减 1。通常用于 0 表示背景且背景本身不包含在数据集所有类别中的数据集(例如 ADE20k)。背景标签将被替换为 255。
**返回:** `~image_processing_base.BatchFeature`
- **data** (`dict`) -- 由 __call__ 方法返回的列表/数组/张量字典(例如 'pixel_values')。
- **tensor_type** (`Union[None, str, TensorType]`,*可选*) -- 您可以在此处指定 tensor_type,以便在初始化时将 PyTorch/Numpy 张量中的整数列表进行转换。
#### post_process_semantic_segmentation[[transformers.BeitImageProcessorPil.post_process_semantic_segmentation]]
```python
post_process_semantic_segmentation(outputs, target_sizes: list[tuple] | None = None, return_segmentation_scores: bool = False)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/image_processing_pil_beit.py#L169)
**参数:**
outputs ([BeitForSemanticSegmentation](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForSemanticSegmentation)):模型的原始输出。
target_sizes (`list[Tuple]`,长度为 `batch_size`,*可选*) : 与每个预测所需的最终尺寸(高度、宽度)对应的元组列表。如果未设置,预测结果将不会被调整大小。
return_segmentation_scores (`bool`,*可选*,默认为 `False`):是否同时返回分割分数和分割图。当为 `True` 时,返回列表中的每个元素都是一个 `SemanticSegmentationPostProcessorOutput`,包含字段 `segmentation`(类别 ID,形状为 `(height, width)`)和 `segmentation_scores`(形状为 `(num_classes, height, width)`)。
**返回:** `list[torch.Tensor]` 或 `list[SemanticSegmentationPostProcessorOutput]`
当 `return_segmentation_scores=False`(默认值)时,返回一个长度为 `batch_size` 的列表,其中每个元素都是形状为 `(height, width)` 且包含类别 ID 的分割图。当 `return_segmentation_scores=True` 时,返回一个 `SemanticSegmentationPostProcessorOutput` 列表,包含字段 `segmentation`(类别 ID,形状为 `(height, width)`)和 `segmentation_scores`(形状为 `(num_classes, height, width)`)。在这两种情况下,`(height, width)` 均对应目标尺寸(如果指定了 `target_sizes`)。
将 [BeitForSemanticSegmentation](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForSemanticSegmentation) 的输出转换为语义分割图。
## BeitModel[[transformers.BeitModel]]
#### transformers.BeitModel[[transformers.BeitModel]]
```python
transformers.BeitModel(config: BeitConfig, add_pooling_layer: bool = True)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L486)
**参数:**
config ([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig)):模型配置类,包含模型的所有参数。通过配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
add_pooling_layer (`bool`,*可选*,默认为 `True`):是否添加池化层
原始的 Beit 模型,输出原始隐藏状态,顶部未添加任何特定头。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.BeitModel.forward]]
```python
forward(pixel_values: Tensor, bool_masked_pos: typing.Optional[torch.BoolTensor] = None, interpolate_pos_encoding: bool = False, attention_mask: typing.Optional[torch.Tensor] = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L512)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`):与输入图像对应的张量。可以使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 获取像素值。有关详细信息,请参阅 [BeitImageProcessor.__call__()](/docs/transformers/v5.23.0/zh/model_doc/molmo2#transformers.Molmo2ImageProcessor.__call__)(`processor_class` 使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 处理图像)。
bool_masked_pos (`torch.BoolTensor`,形状为 `(batch_size, num_patches)`,*可选*):布尔掩码位置。指示哪些 patch 被掩码(1),哪些未被掩码(0)。
interpolate_pos_encoding (`bool`,*可选*,默认为 `False`):是否对预训练的位置编码进行插值。
attention_mask (`torch.Tensor`,形状为 `(batch_size, sequence_length)`,*可选*):用于避免对填充(padding)标记索引执行注意力机制的掩码。掩码值取自 `[0, 1]`: - 1 表示**未掩码**的标记, - 0 表示**已掩码**的标记。 [什么是注意力掩码?](../glossary#attention-mask)
**返回:** [BeitModelOutputWithPooling](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.models.beit.modeling_beit.BeitModelOutputWithPooling) 或 `tuple(torch.Tensor)`
一个 [BeitModelOutputWithPooling](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.models.beit.modeling_beit.BeitModelOutputWithPooling) 或 `torch.Tensor` 元组(如果传入了 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig))和输入。
[BeitModel](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitModel) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **last_hidden_state**(形状为 `(batch_size, sequence_length, hidden_size)` 的 `torch.Tensor`)-- 模型最后一层输出的隐藏状态序列。
- **pooler_output**(形状为 `(batch_size, hidden_size)` 的 `torch.Tensor`)-- 如果 *config.use_mean_pooling* 设置为 True,则为 patch token 最后一层隐藏状态的平均值(不包括 *[CLS]* token)。如果设置为 False,则返回 *[CLS]* token 的最终隐藏状态。
- **hidden_states** (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层的输出,以及每一层的输出),形状为 `(batch_size, sequence_length, hidden_size)`。
模型在每一层输出处的隐藏状态,以及可选的初始嵌入输出。
- **attentions** (`tuple(torch.Tensor)`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
经过注意力 softmax 后的注意力权重,用于在自注意力头中计算加权平均值。
示例:
```python
```
## BeitForMaskedImageModeling[[transformers.BeitForMaskedImageModeling]]
#### transformers.BeitForMaskedImageModeling[[transformers.BeitForMaskedImageModeling]]
```python
transformers.BeitForMaskedImageModeling(config: BeitConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L583)
**参数:**
config ([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig)):模型配置类,包含模型的所有参数。通过配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
带有“语言”建模头的 Beit 模型 Transformer。BEiT 通过预测向量量化变分自编码器(VQ-VAE)的视觉标记来进行掩码图像建模,而 ViT 和 DeiT 等其他视觉模型则预测 RGB 像素值。因此,该类与 [AutoModelForMaskedImageModeling](/docs/transformers/v5.23.0/zh/model_doc/auto#transformers.AutoModelForMaskedImageModeling) 不兼容,如果您希望使用 BEiT 进行掩码图像建模,需要直接使用 [BeitForMaskedImageModeling](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForMaskedImageModeling)。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.BeitForMaskedImageModeling.forward]]
```python
forward(pixel_values: typing.Optional[torch.Tensor] = None, bool_masked_pos: typing.Optional[torch.BoolTensor] = None, labels: typing.Optional[torch.Tensor] = None, interpolate_pos_encoding: bool = False, attention_mask: typing.Optional[torch.Tensor] = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L600)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`,*可选*) : 与输入图像对应的张量。可以使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 获取像素值。有关详细信息,请参阅 [BeitImageProcessor.__call__()](/docs/transformers/v5.23.0/zh/model_doc/molmo2#transformers.Molmo2ImageProcessor.__call__)(`processor_class` 使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 处理图像)。
bool_masked_pos (`torch.BoolTensor`,形状为 `(batch_size, num_patches)`):布尔掩码位置。指示哪些 patch 被掩码(1),哪些未被掩码(0)。
labels (`torch.LongTensor`,形状为 `(batch_size,)`,*可选*) : 用于计算图像分类/回归损失的标签。索引应在 `[0, ..., config.num_labels - 1]` 范围内。如果 `config.num_labels == 1`,则计算回归损失(均方损失);如果 `config.num_labels > 1`,则计算分类损失(交叉熵)。
interpolate_pos_encoding (`bool`,*可选*,默认为 `False`):是否对预训练的位置编码进行插值。
attention_mask (`torch.Tensor`,形状为 `(batch_size, sequence_length)`,*可选*):用于避免对填充(padding)标记索引执行注意力机制的掩码。掩码值取自 `[0, 1]`: - 1 表示**未掩码**的标记, - 0 表示**已掩码**的标记。 [什么是注意力掩码?](../glossary#attention-mask)
**返回:** [MaskedLMOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.MaskedLMOutput) 或 `tuple(torch.Tensor)`
一个 [MaskedLMOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.MaskedLMOutput) 或 `torch.Tensor` 元组(如果传入了 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig))和输入。
[BeitForMaskedImageModeling](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForMaskedImageModeling) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **loss** (`torch.Tensor`,形状为 `(1,)`,*可选*,当提供 `labels` 时返回) -- 掩码语言建模(MLM)损失。
- **logits**(形状为 `(batch_size, sequence_length, config.vocab_size)` 的 `torch.Tensor`)-- 语言建模头的预测分数(SoftMax 之前每个词汇表 token 的分数)。
- **hidden_states** (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层的输出,以及每一层的输出),形状为 `(batch_size, sequence_length, hidden_size)`。
模型在每一层输出处的隐藏状态,以及可选的初始嵌入输出。
- **attentions** (`tuple(torch.Tensor)`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
经过注意力 softmax 后的注意力权重,用于在自注意力头中计算加权平均值。
示例:
```python
>>> from transformers import AutoImageProcessor, BeitForMaskedImageModeling
>>> import torch
>>> from PIL import Image
>>> import requests
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> image_processor = AutoImageProcessor.from_pretrained("microsoft/beit-base-patch16-224-pt22k")
>>> model = BeitForMaskedImageModeling.from_pretrained("microsoft/beit-base-patch16-224-pt22k")
>>> num_patches = (model.config.image_size // model.config.patch_size) ** 2
>>> pixel_values = image_processor(images=image, return_tensors="pt").pixel_values
>>> # create random boolean mask of shape (batch_size, num_patches)
>>> bool_masked_pos = torch.randint(low=0, high=2, size=(1, num_patches)).bool()
>>> outputs = model(pixel_values, bool_masked_pos=bool_masked_pos)
>>> loss, logits = outputs.loss, outputs.logits
>>> list(logits.shape)
[1, 196, 8192]
```
## BeitForImageClassification[[transformers.BeitForImageClassification]]
#### transformers.BeitForImageClassification[[transformers.BeitForImageClassification]]
```python
transformers.BeitForImageClassification(config: BeitConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L675)
**参数:**
config ([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig)):模型配置类,包含模型的所有参数。通过配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
Beit 模型,顶部带有图像分类头(在 patch token 的最终隐藏状态平均值之上添加一个线性层),例如用于 ImageNet。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.BeitForImageClassification.forward]]
```python
forward(pixel_values: typing.Optional[torch.Tensor] = None, labels: typing.Optional[torch.Tensor] = None, interpolate_pos_encoding: bool = False, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L688)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`,*可选*) : 与输入图像对应的张量。可以使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 获取像素值。有关详细信息,请参阅 [BeitImageProcessor.__call__()](/docs/transformers/v5.23.0/zh/model_doc/molmo2#transformers.Molmo2ImageProcessor.__call__)(`processor_class` 使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 处理图像)。
labels (`torch.LongTensor`,形状为 `(batch_size,)`,*可选*) : 用于计算图像分类/回归损失的标签。索引应在 `[0, ..., config.num_labels - 1]` 范围内。如果 `config.num_labels == 1`,则计算回归损失(均方损失);如果 `config.num_labels > 1`,则计算分类损失(交叉熵)。
interpolate_pos_encoding (`bool`,*可选*,默认为 `False`):是否对预训练的位置编码进行插值。
**返回:** [ImageClassifierOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.ImageClassifierOutput) 或 `tuple(torch.Tensor)`
一个 [ImageClassifierOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.ImageClassifierOutput) 或 `torch.Tensor` 元组(如果传入了 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig))和输入。
[BeitForImageClassification](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForImageClassification) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **loss** (`torch.Tensor`,形状为 `(1,)`,*可选*,当提供 `labels` 时返回) -- 分类损失(如果 config.num_labels==1,则为回归损失)。
- **logits**(形状为 `(batch_size, config.num_labels)` 的 `torch.Tensor`)-- 分类(或当 config.num_labels==1 时为回归)得分(SoftMax 之前)。
- **hidden_states** (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每个阶段输出的一个张量),形状为 `(batch_size, sequence_length, hidden_size)`。模型在每个阶段输出处的隐藏状态(也称为特征图)。
- **attentions** (`tuple(torch.Tensor)`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, patch_size, sequence_length)`。
经过注意力 softmax 后的注意力权重,用于在自注意力头中计算加权平均值。
示例:
```python
>>> from transformers import AutoImageProcessor, BeitForImageClassification
>>> import torch
>>> from datasets import load_dataset
>>> dataset = load_dataset("huggingface/cats-image")
>>> image = dataset["test"]["image"][0]
>>> image_processor = AutoImageProcessor.from_pretrained("microsoft/beit-base-patch16-224-pt22k")
>>> model = BeitForImageClassification.from_pretrained("microsoft/beit-base-patch16-224-pt22k")
>>> inputs = image_processor(image, return_tensors="pt")
>>> with torch.no_grad():
... logits = model(**inputs).logits
>>> # model predicts one of the 1000 ImageNet classes
>>> predicted_label = logits.argmax(-1).item()
>>> print(model.config.id2label[predicted_label])
...
```
## BeitForSemanticSegmentation[[transformers.BeitForSemanticSegmentation]]
#### transformers.BeitForSemanticSegmentation[[transformers.BeitForSemanticSegmentation]]
```python
transformers.BeitForSemanticSegmentation(config: BeitConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L978)
**参数:**
config ([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig)):模型配置类,包含模型的所有参数。通过配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
在顶部添加语义分割头的 Beit 模型,例如用于 ADE20K、CityScapes。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.BeitForSemanticSegmentation.forward]]
```python
forward(pixel_values: typing.Optional[torch.Tensor] = None, labels: typing.Optional[torch.Tensor] = None, interpolate_pos_encoding: bool = False, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/beit/modeling_beit.py#L1000)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`,*可选*) : 与输入图像对应的张量。可以使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 获取像素值。有关详细信息,请参阅 [BeitImageProcessor.__call__()](/docs/transformers/v5.23.0/zh/model_doc/molmo2#transformers.Molmo2ImageProcessor.__call__)(`processor_class` 使用 [BeitImageProcessor](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitImageProcessor) 处理图像)。
labels (`torch.LongTensor`,形状为 `(batch_size, height, width)`,*可选*) : 用于计算损失的真实语义分割图。索引应在 `[0, ..., config.num_labels - 1]` 范围内。如果 `config.num_labels > 1`,则计算分类损失(交叉熵)。
interpolate_pos_encoding (`bool`,*可选*,默认为 `False`):是否对预训练的位置编码进行插值。
**返回:** [SemanticSegmenterOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.SemanticSegmenterOutput) 或 `tuple(torch.Tensor)`
一个 [SemanticSegmenterOutput](/docs/transformers/v5.23.0/zh/main_classes/output#transformers.modeling_outputs.SemanticSegmenterOutput) 或 `torch.Tensor` 元组(如果传入了 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置([BeitConfig](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitConfig))和输入。
[BeitForSemanticSegmentation](/docs/transformers/v5.23.0/zh/model_doc/beit#transformers.BeitForSemanticSegmentation) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **loss** (`torch.Tensor`,形状为 `(1,)`,*可选*,当提供 `labels` 时返回) -- 分类损失(如果 config.num_labels==1,则为回归损失)。
- **logits**(形状为 `(batch_size, config.num_labels, logits_height, logits_width)` 的 `torch.Tensor`)-- 每个像素的分类分数。
返回的 logits 大小不一定与作为输入传入的 `pixel_values` 相同。这样设计是为了避免进行两次插值,从而在用户需要将 logits 调整为原始图像尺寸作为后处理时损失部分质量。您应始终检查 logits 的形状,并根据需要进行调整。
- **hidden_states** (`tuple(torch.Tensor)`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每个层输出的一个张量),形状为 `(batch_size, patch_size, hidden_size)`。
模型在每一层输出处的隐藏状态,以及可选的初始嵌入输出。
- **attentions** (`tuple(torch.Tensor)`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, patch_size, sequence_length)`。
经过注意力 softmax 后的注意力权重,用于在自注意力头中计算加权平均值。
示例:
```python
>>> from transformers import AutoImageProcessor, BeitForSemanticSegmentation
>>> from PIL import Image
>>> import requests
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> image_processor = AutoImageProcessor.from_pretrained("microsoft/beit-base-finetuned-ade-640-640")
>>> model = BeitForSemanticSegmentation.from_pretrained("microsoft/beit-base-finetuned-ade-640-640")
>>> inputs = image_processor(images=image, return_tensors="pt")
>>> outputs = model(**inputs)
>>> # logits are of shape (batch_size, num_labels, height, width)
>>> logits = outputs.logits
```